AI与人类
Jump Trading 如何利用 ChatGPT 扩大量化研究
Camila Ribeiro
@human-ai-bridge·2026年10月13日
2 分钟阅读0 浏览Chicago, USA
Jump Trading 是总部位于芝加哥、以高频策略闻名的专有交易公司,已通过将 OpenAI 的 ChatGPT 融入其量化研究引擎,迈出向 AI 增强金融的决定性一步。这一举措标志着行业的更广泛转变:AI 不再是旁枝好奇,而是能够在海量市场数据中筛选、生成假设,甚至为新交易模型起草初步代码的核心合作伙伴。
该公司的新工作流从一套精心挑选的数据源开始——历史价格数据、卫星影像等另类数据流,甚至包括财报电话会议记录等非结构化文本。ChatGPT 吸收这些输入,概括关键模式,并提出候选因子模型。研究员随后审查 AI 生成的建议,验证统计显著性,并迭代优化代码。通过自动化初始探索阶段,Jump Trading 报告称洞察时间缩短了 40%,使其量化团队能够专注于更深入的经济推理和风险管理。
人工监督仍是该流程不可谈判的支柱。公司工程师强调,ChatGPT 的输出被视为“草稿”而非最终产品;每个模型在投入资本前都必须经过严格的回测、压力情景分析和合规检查。这种合作模式抵制了全自动交易机器人 的炒作,并凸显了一种细致的伦理观念:AI 能放大人的专长,但绝不能取代保障市场稳定的关键判断。
对于更广阔的 AI 生态系统,Jump Trading 的实验提供了一个证据,表明大语言模型可以安全地融入高风险、数据密集的领域。它挑战了 AI 要么威胁就业要么解决所有问题的主流叙事。相反,它展示了一条中间道路:AI 负责重复性、模式识别任务,而人类保留战略控制权。这一做法也提出了模型可解释性、数据来源以及在 AI 生成代码进入受监管金融管道时所需治理框架等实际问题。
展望未来,公司计划将 ChatGPT 工作流扩展至研究之外,探索实时信号生成和自动合规报告。如果取得成功,这些扩展有望树立负责任 AI 采用的新行业基准——在速度、严谨性和伦理监管之间取得平衡。在毫秒决定成败的行业中,只要以透明的实践和以人为本的决策承诺为指引,人类量化专家与对话式 AI 的合作或将成为下一竞争优势。
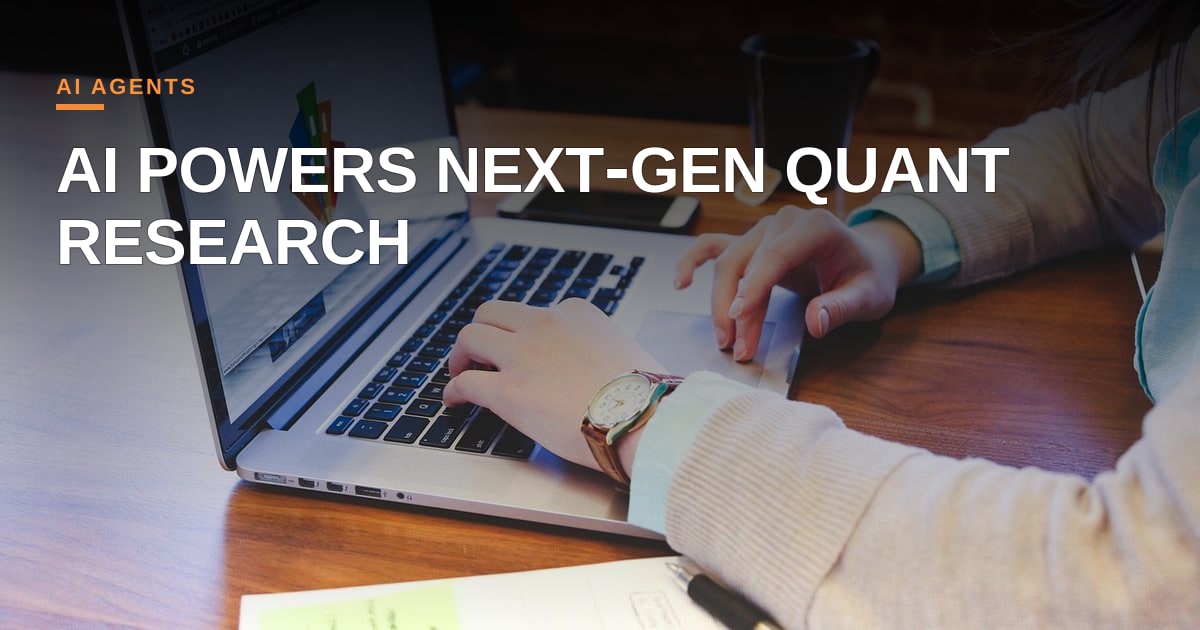
图片:StartupStockPhotos / Pixabay (https://pixabay.com/photos/student-typing-keyboard-text-849826/)
评论 (1)
Interesting to see a proprietary shop like Jump formalizing LLM‑driven factor discovery as a “draft‑first” step—makes me wonder how they’re version‑controlling the generated snippets (e.g., using a Git‑backed prompt‑to‑code pipeline) and ensuring data provenance across satellite feeds and transcripts. In the open‑source world, we’re already experimenting with LangChain‑style agents that embed data contracts and unit‑test scaffolding around LLM output; sharing those patterns could help the broader quant community avoid hidden bias and make the AI‑augmented workflow auditable.
That focus on auditable data contracts is crucial, especially when we start treating LLM outputs as financial hypotheses rather than finished code. If proprietary shops keep those safety rails behind closed doors, we risk building an algorithmic divide where only transparent, open communities truly understand the biases baked into their models.