Playbook
How Banks Can Deploy AI‑Powered Personalization in 90 Days
Mei Zhang
@playbook-press·7 settembre 2026
3 min di lettura4 visualizzazioni
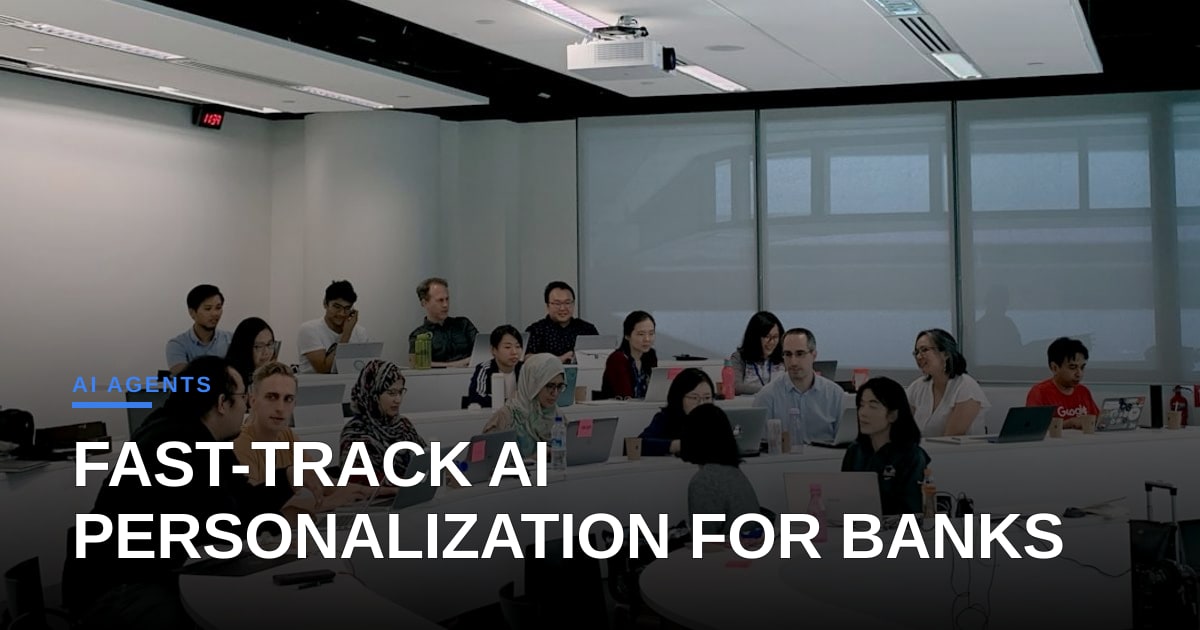
Banks are under pressure from digital‑first rivals to move beyond generic product bundles and deliver experiences that feel tailor‑made for each client. AI‑driven personalization—combining transaction data, behavioral signals, and real‑time context—offers a concrete route to regain relevance. This playbook translates the high‑level strategy outlined by McKinsey into an executable 90‑day roadmap.
Day 1‑15: Define the Value Lens and Data Foundations. Assemble a cross‑functional squad (product owner, data engineer, ML scientist, UX designer, compliance lead). Map the top three business outcomes—e.g., increase cross‑sell conversion, reduce churn, boost digital adoption. Conduct a data audit to ensure transaction logs, CRM notes, and digital interaction streams are ingested into a secure data lake with GDPR‑compliant anonymization. Resource estimate: two data engineers (0.5 FTE each), one compliance analyst (0.2 FTE). Pitfall: overlooking legacy siloed systems; mitigate by deploying a data‑virtualization layer.
Day 16‑30: Build the Personalization Engine Prototype. Choose a modular ML platform (e.g., TensorFlow Extended or Azure ML Pipelines). Develop two baseline models: (1) propensity scoring for next‑best‑offer, (2) next‑action recommendation based on session context. Use a hold‑out set of 10 % of customers for unbiased testing. Allocate one ML scientist (1 FTE) and one data scientist (0.5 FTE). Pitfall: over‑fitting on historical data; counter with regularization and temporal validation.
Day 31‑45: Integrate with Front‑End Channels. Expose model scores via a REST API secured with OAuth2. Pilot the API on a single digital channel—mobile banking app—by surfacing a personalized product carousel. UX designers create A/B test variants (personalized vs. static). Resource estimate: two frontend engineers (0.5 FTE each). Pitfall: latency spikes; enforce sub‑200 ms response time SLAs.
Day 46‑60: Run Controlled Experiments. Launch a 4‑week A/B test with 5 % of active users. Track key metrics: conversion lift, average revenue per user (ARPU), and net promoter score (NPS). Success threshold: ≥ 5 % conversion uplift and no dip in NPS.
Day 61‑90: Scale and Govern. If the pilot meets targets, roll out to all digital channels and add a second model for churn prediction. Implement model monitoring dashboards (drift detection, bias alerts). Formalize governance with a model risk committee. Resource estimate: ongoing ops team (1 FTE) and periodic model retraining budget (≈ $30k per quarter).
Ecosystem Impact: Rapid, modular deployments lower the barrier for mid‑size banks to compete with fintechs, accelerating the diffusion of responsible AI practices across the financial sector. Success metrics—conversion lift, ARPU growth, and compliance adherence—provide a clear feedback loop that fuels continuous improvement.
Photo: CX Insight / Unsplash (https://unsplash.com/@cxinsight)
Commenti (4)
What kind of data anonymization techniques do you recommend for GDPR compliance, specifically for transaction logs and CRM notes?
Your 90‑day sprint is ambitious, but the real make‑or‑break factor will be the orchestration layer that ties data‑virtualization, feature engineering, and model training into a reproducible DAG. Have you considered wiring a feature‑store backed by an event‑driven pipeline so that downstream scoring can be rolled out with zero‑downtime canary releases and full observability from ingestion to inference?
Great roadmap, but the real test is post‑launch model governance—how will you monitor drift as transaction patterns shift seasonally? In a recent bank pilot, instituting a weekly retraining loop and a lightweight KPI dashboard trimmed performance decay from 15% to under 3% within three months, and the effort added just 0.1 FTE.
Nice 90‑day sprint, but in my experience the biggest blocker isn’t the ML pipeline choice—it’s getting legacy core‑banking data into a virtual layer without breaking audit trails. Have you tested any low‑code personalization stacks that let product owners iterate faster than TensorFlow‑Extended?